DevSecOps Operations
Risk Acceptance in 2026: Designing an Audit-Proof Exception Workflow
Pass your next SOC 2 audit with defensible remediation records. Learn how InstaSLA turns dismissed security alerts into audit-proof risk acceptance workflows
By InstaSLA Superadmin · Published · 15 min read
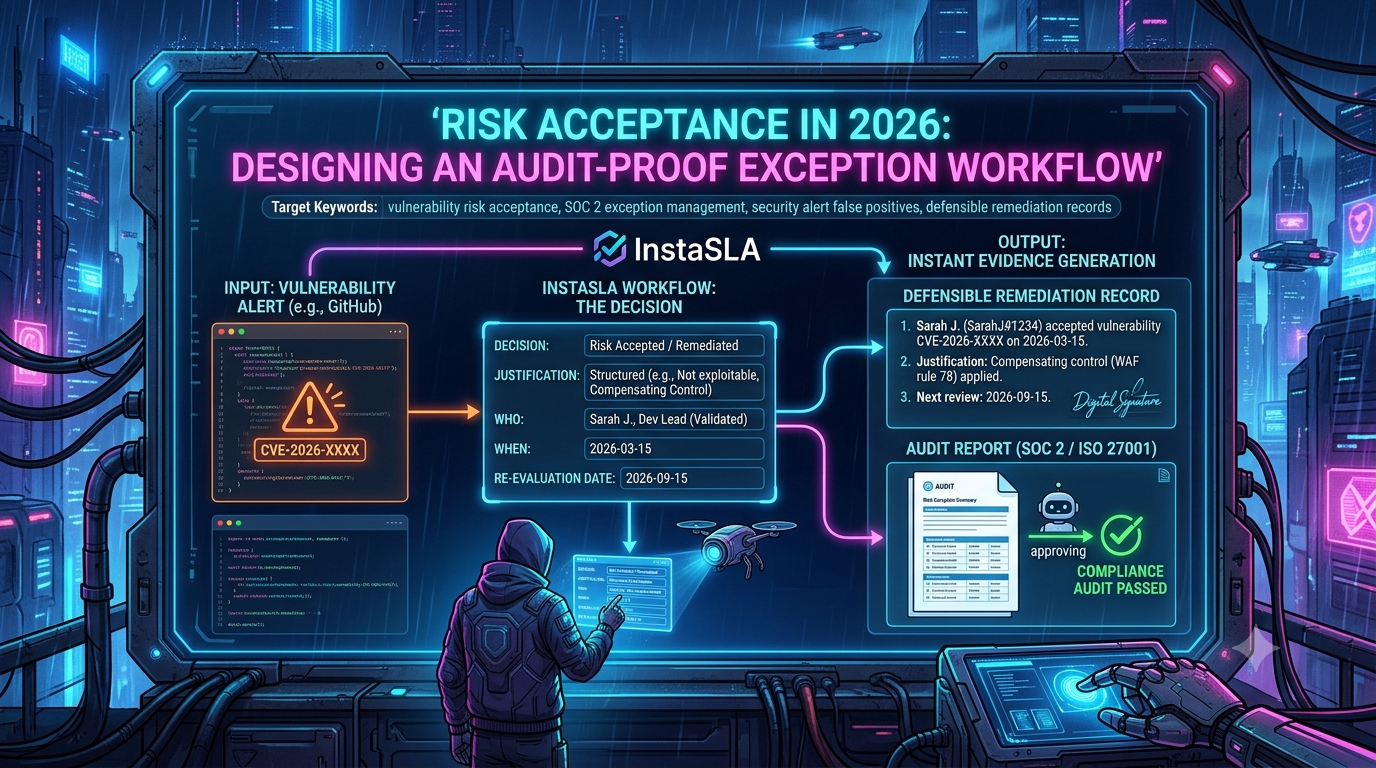
Risk Acceptance in 2026: Designing an Audit-Proof Exception Workflow
As a Compliance Officer, there are few things more anxiety-inducing than the final review phase of a SOC 2 Type II or ISO 27001 audit, only to discover that your engineering team has been quietly dismissing critical security alerts. The auditor pulls a sample of ten "Critical" GitHub Dependabot or GitHub Advanced Security alerts from the past quarter. You look at the logs, and most of them carry a one-line, checkbox-style reason: Dismissed — Tolerable Risk or Dismissed — Won't Fix, maybe with a sentence of free-text underneath if you're lucky.
There's a reason code. There's sometimes a comment. But there is no business justification tied to an owner, no record of who was actually authorized to accept that risk, and no expiration date forcing anyone to look at it again. When the auditor asks, "Who approved leaving this critical remote code execution vulnerability unpatched, and why?", your only defense is to scramble, ping a lead engineer on Slack, and hope they remember a decision made four months ago.
This is how audits are failed, or at best, how organizations end up with severe qualified opinions and non-conformities.
In the high-velocity software development landscape of 2026, where AI coding assistants are pushing code at unprecedented speeds, security scanners are generating more noise than ever before. Developers are naturally inclined to clear their dashboards to keep shipping. However, for a Compliance Officer, this unstructured approach to vulnerability management is a ticking time bomb.
The truth is that auditors do not expect you to have zero vulnerabilities. But they absolutely expect a defensible, documented process for why an alert was ignored. This article explores the anatomy of a failed exception process and walks through how modern teams are using platforms like InstaSLA to force a structured risk acceptance workflow, instantly generating the defensible remediation records you need to pass your next audit with flying colors.
The "Zero Vulnerabilities" Myth vs. Real Auditor Expectations
There is a common misconception among engineering teams (and sometimes junior security analysts) that passing a compliance audit requires a completely clean security scan. This "zero vulnerability" mindset is not only technically impossible in modern, complex microservice architectures, but it is also operationally destructive.
If a team attempts to patch every single low-severity flaw or theoretical vulnerability, they will grind product development to a halt. Furthermore, they will inevitably break legacy systems by blindly forcing dependency updates.
Auditors from accredited CPA firms evaluating your SOC 2 Trust Services Criteria — specifically the Security common criteria, and within it CC7.1 (detection and monitoring procedures that identify configuration changes introducing new vulnerabilities and susceptibility to newly discovered ones) and CC7.2 (monitoring for anomalies and use of threat intelligence) — understand this reality. So do ISO 27001 auditors assessing Annex A control 8.8, "Management of Technical Vulnerabilities" (the 2022 revision's replacement for the old 12.6.1 control), which requires you to obtain information about technical vulnerabilities, evaluate your exposure, and take appropriate, risk-based action on a defined timeline. They know that software involves risk. What they are evaluating is your governance over that risk — and CC7.1 in particular is one of the most heavily sampled controls in a SOC 2 Type II fieldwork, with vulnerability assessment and patch/exception records among the most-requested evidence items across all four quarters of the audit period.
When an auditor looks at your vulnerability management program, they are asking three fundamental questions:
- Do you have visibility? (Are you scanning for vulnerabilities?)
- Do you have an SLA? (Do you have a policy that dictates how fast you fix things based on severity?)
- Do you have control over deviations? (When you inevitably breach an SLA or decide not to fix something, how is that governed?)
It is this third question that trips up most modern SaaS companies. Vulnerability risk acceptance is a legitimate and necessary business function. Sometimes, a vulnerable library is deployed in an isolated, internal test environment with no internet access. Sometimes, a patch would cause unacceptable downtime during a critical holiday sales period. Sometimes, a scanner flags a vulnerability that is technically impossible to exploit in the context of your specific application architecture.
These are all valid reasons to bypass remediation. However, a valid reason means nothing if it is not documented in a structured, auditable format. And the stakes for getting this wrong keep rising: IBM's 2026 Cost of a Data Breach Report, based on 602 breached organizations surveyed by the Ponemon Institute, put the global average cost of a breach at a record $4.99 million — up 12% year over year — with breaches in the US averaging $11.5 million. The same report found that the average breach now takes 247 days to identify and contain, up from prior years, meaning an exception nobody revisits can sit exploitable for the better part of a year before anyone even notices the fallout.
Why the Exception Backlog Exploded in 2026
The "quietly dismissed alert" problem described above isn't a fringe issue anymore — it's the default state of most engineering organizations, and the numbers explain why manual, developer-driven triage has stopped being a viable strategy.
- The alert volume is no longer human-scale. OX Security's 2026 Application Security Benchmark found that organizations now average roughly 865,000 open security alerts each, up 52% year over year, driven in large part by the surge in AI-assisted code output.
- Security debt is now the norm, not the exception. Veracode's 2026 State of Software Security report, drawn from 1.6 million applications and 141 million findings, found that 82% of organizations now carry security debt, and the median "fix half-life" — the time it takes to close half of all discovered flaws — sits at 243 days.
- The exploit window has collapsed. Research from Mondoo found that the average time between a vulnerability's disclosure and the appearance of working exploit code dropped from roughly 63 days to about 5 days in 2026, which means an exception granted under last year's threat model can become critical practically overnight.
- Most "critical" alerts aren't actually the ones that matter. Datadog's 2026 research found that only about 18% of vulnerabilities initially labeled critical by scanners remain critical once real runtime and reachability context is applied — reinforcing why a structured, risk-based exception process (rather than blanket dismissal or blanket remediation) is the only approach that scales.
- AI-generated code is accelerating the whole cycle. Veracode's ongoing GenAI Code Security testing across 100+ large language models found that roughly 45% of AI-generated code samples introduce an OWASP Top 10 vulnerability, and its Spring 2026 retest found security pass rates still stuck at around 55% even as syntax correctness climbed above 95%. Separately, Cycode's 2026 survey of 400+ security practitioners found that 100% of organizations now have AI-generated code in their codebases, but 81% of security teams say they lack visibility into which code was AI-written in the first place.
Put together, these numbers describe an environment where the volume of things a developer could dismiss vastly outpaces any team's capacity to review each decision by hand — which is exactly the condition that makes ungoverned, individual alert-dismissal so dangerous, and structured exception workflows so necessary.
The Danger of Developer-Driven Risk Acceptance
The root cause of most compliance failures regarding vulnerability management stems from where the power to close alerts resides. In many organizations, developers have the permissions to dismiss security alerts directly within their IDEs, GitHub, or GitLab repositories.
It's worth being precise about what "dismissing an alert" actually involves on a platform like GitHub, because the gap isn't a total absence of data — it's the absence of governance around that data. GitHub Dependabot alerts require a structured reason when dismissed (fix already started, alert is inaccurate, vulnerable code isn't actually used, no bandwidth to fix, or risk is tolerable to the project), plus an optional free-text comment. GitHub Advanced Security code-scanning alerts work similarly, with three built-in reasons — false positive, won't fix, or used in tests — and their own comment field. So the ten alerts your auditor sampled probably do have a reason attached. What they almost certainly don't have is a record of who was authorized to make that call, whether anyone with the right seniority reviewed it, or when it's scheduled to be revisited. A dropdown reason code is not, by itself, a governed risk acceptance — and that distinction is exactly what auditors are trained to probe.
Faced with looming sprint deadlines and overwhelming alert fatigue, developers often treat security scanners like a nuisance. The path of least resistance is to select a reason from the dropdown and move on. This creates the "Black Hole of Exception Management." The dangers include:
1. Unverified Security Alert False Positives
Developers frequently classify alerts as security alert false positives simply because they do not immediately understand the exploit path. A true false positive means the scanner made a mistake. If a developer claims a finding is a false positive without providing technical proof or a secondary review, they are effectively self-approving the acceptance of a potential risk. Auditors view unverified false positives as unmitigated risks — and a bare "Inaccurate" or "False positive" selection in a scanner's UI, with no supporting evidence attached, reads exactly like a self-approval when an auditor samples it.
2. Lack of Segregation of Duties
A core tenet of both SOC 2 and ISO 27001 is segregation of duties — formally, ISO 27001:2022 Annex A control 5.3, which requires that conflicting duties and areas of responsibility be separated so no single person can both take a sensitive action and approve, verify, or conceal it. The person who wrote the vulnerable code, or the person whose performance is measured by how fast the code ships, should not be the sole authority on whether a security risk is acceptable. When developers unilaterally close alerts, there is zero oversight, and that single-actor pattern is precisely what Annex A 5.3 exists to prevent.
3. Infinite Exceptions
When an alert is manually closed in a repository without a tracking system, it is closed forever. But risks change. A vulnerability that is acceptable today might become a critical threat tomorrow if a new exploit is published — and as the exploit-timeline data above shows, "tomorrow" can now arrive in days rather than months — or if the architecture of the application changes, exposing a previously internal service to the public internet. Without a mechanism to revisit accepted risks, you are building a hidden mountain of security debt.
4. Ephemeral "Slack" Evidence
When auditors demand proof of why a vulnerability was accepted, compliance teams often resort to scraping Slack channels or hunting through unstructured Jira comments to find a conversation where an engineering manager said, "Yeah, we don't need to fix that." Chat logs are not a system of record. They lack formal approval workflows, consistent formatting, and guaranteed retention, making them unacceptable as audit evidence.
If any of this sounds familiar from outside the SOC 2 / ISO 27001 world: it's the same underlying discipline that federal agencies and contractors formalize as a Plan of Action and Milestones (POA&M) under NIST SP 800-37 and NIST SP 800-171 — a documented weakness, an owner, a remediation approach, and a target date, tracked until closure or formal risk acceptance. Commercial compliance frameworks describe the same governance goal in different language; the mechanics your exception workflow needs are nearly identical either way.
Designing the Audit-Proof Exception Workflow
To transition from ad-hoc alert dismissal to a mature SOC 2 exception management program, compliance officers must partner with engineering leadership to implement a structured, four-pillar workflow.
Pillar 1: Categorization and Justification
Every dismissed alert must have a categorized reason and a written justification. A dropdown menu is essential for standardizing data — and it's worth noting that GitHub's own built-in reason codes (Inaccurate, Not Used, No Bandwidth, Tolerable Risk, Fix Started, False Positive, Won't Fix, Used in Tests) already map cleanly onto the categories a mature program needs; the gap is layering approval, evidence, and expiration on top of them. Acceptable categories usually include:
- False Positive: The vulnerability does not exist in the code. (Requires technical proof.)
- Mitigating Controls: The vulnerability exists, but compensating controls (like a Web Application Firewall rule or network isolation) reduce the risk to an acceptable level.
- Acceptable Risk (Business Context): The vulnerability exists, but the asset is low-value, non-production, or the cost of remediation far outweighs the potential impact.
- Operational Blocker: A patch exists, but applying it will break a critical production dependency. (This is a temporary delay, not a permanent acceptance.)
Pillar 2: Elevated Approvals
Risk cannot be accepted at the individual contributor level. The workflow must route the exception request to an appropriate authority based on the severity of the alert.
- Low/Medium Severity: Can be approved by an Engineering Manager or Lead.
- High Severity: Requires approval from the Director of Engineering or a Security Analyst.
- Critical Severity: Requires explicit sign-off from the CISO, VP of Engineering, or the designated Risk Officer.
Pillar 3: Time-Bound Exceptions
No risk should be accepted indefinitely. Every exception must have a mandatory expiration date. For a critical operational blocker, the exception might only be valid for 14 days while a workaround is engineered. For a low-severity issue in an internal tool, the exception might be valid for one year — though given how fast exploit timelines are now moving, even "low severity, one year" exceptions increasingly warrant a check-in well before renewal. When the expiration date hits, the alert must automatically reopen and re-enter the standard SLA workflow.
Pillar 4: Immutable Audit Trails
The entire lifecycle of the exception — who requested it, the written justification, who approved it, the timestamp of approval, and the expiration date — must be logged in an immutable database that cannot be tampered with by developers.
How InstaSLA Forces Compliance and Generates Evidence
Implementing a four-pillar workflow sounds great in theory, but in practice, trying to manage this via manual Jira tickets or spreadsheets usually collapses under the sheer volume of modern development speeds — especially once you're staring down a backlog measured in the hundreds of thousands of alerts. This is where specialized SLA and exception management platforms become mandatory for compliance teams in 2026.
Platforms like InstaSLA are designed explicitly to bridge the gap between developer velocity and strict compliance requirements. By integrating directly into the CI/CD pipeline and GitHub repositories, InstaSLA removes the manual overhead of exception handling and forces the necessary governance.
Here is how InstaSLA operationalizes the audit-proof workflow:
1. Removing the "Easy Out"
First, organizations use InstaSLA in conjunction with branch protection rules to prevent developers from simply dismissing alerts in GitHub. If an alert breaches the company's defined SLA (e.g., 14 days for a High severity issue), InstaSLA automatically blocks the developer from merging any new code into the main branch.
The developer cannot bypass this block by quietly selecting a dismiss reason. The only way to unblock their merge is to either fix the code or initiate a formal Exception Request through the InstaSLA platform.
2. Forcing Structured Requests
When a developer initiates an Exception Request, InstaSLA forces them into the structured workflow. The developer must select a standardized reason (False Positive, Mitigating Control, etc.), provide a detailed written justification, and propose an expiration date.
3. Automated Routing and Approvals
InstaSLA automatically routes the request to the correct approver based on the severity of the vulnerability and the repository owner. If a developer requests an exception for a "Critical" vulnerability, InstaSLA alerts the CISO or Security Lead. The approver can review the context, read the justification, and either approve or reject the request directly within the platform.
4. Continuous Monitoring and Re-Opening
If the exception is approved, InstaSLA unblocks the developer's merge pipeline. However, the platform continues to track the expiration date. If a developer received a 30-day exception for an operational blocker, on day 31, InstaSLA automatically revokes the exception, reopens the vulnerability, flags it as an SLA breach, and re-applies the merge block. This guarantees that temporary exceptions never morph into permanent security debt.
5. Instant "Defensible Remediation Records"
For the Compliance Officer, the most powerful feature of this system is the reporting engine. When the SOC 2 or ISO 27001 auditor requests evidence of your vulnerability management practices, you no longer have to scramble.
Within InstaSLA, you can generate a comprehensive defensible remediation record with a single click. This report details every vulnerability that was flagged, the time to remediation, and most importantly, a pristine audit trail for every single exception.
The auditor will see exactly which alerts were accepted as risks, the business justification for each, the name and title of the person who approved it, and the date it is scheduled to be reviewed again. It provides absolute, irrefutable proof that your organization is not ignoring risk, but actively and responsibly governing it.
Conclusion: Stop Fearing the Auditor
Failing a compliance audit due to poor vulnerability management is entirely preventable. The expectation in 2026 is not perfection; it is process. As organizations adopt AI coding tools and the volume of software output increases — alongside it, the volume of alerts, the shrinking exploit window, and the share of code security teams can't even see into — manual tracking of risk exceptions is a guaranteed path to audit failure.
By moving away from developer-driven, undocumented alert dismissals and embracing a structured, platform-enforced workflow, compliance officers can reclaim control over the security posture. Tools like InstaSLA enforce accountability, prevent infinite exceptions, and automatically generate the defensible remediation records that auditors demand.
Ultimately, designing an audit-proof exception workflow transforms vulnerability management from a chaotic, anxiety-inducing scramble into a predictable, transparent, and mature business process. You can stop fearing the auditor's sample requests, knowing that every accepted risk is backed by undeniable, structured evidence.
Sources
- IBM / Ponemon Institute, Cost of a Data Breach Report 2026 — ibm.com
- ISMS.online, ISO 27001:2022 Annex A Control 8.8 — Management of Technical Vulnerabilities — isms.online
- ISMS.online, ISO 27001:2022 Annex A Control 5.3 — Segregation of Duties — isms.online
- Konfirmity, SOC 2 Vulnerability Management: Key Requirements & Templates (2026) — konfirmity.com
- GitHub Docs, GraphQL API reference — Dependabot
DismissReason— docs.github.com - GitHub,
rest-api-description— code scanning alertdismissed_reason— github.com - OX Security, 2026 Application Security Benchmark (via Pixee, Vulnerability Remediation Statistics 2026) — pixee.ai
- Veracode, 2026 State of Software Security and Spring 2026 GenAI Code Security Update — veracode.com
- Cycode, What 2026 Looks Like (AppSec report roundup) — pixee.ai
- NIST SP 800-37 Rev. 2 / GSA CIO-IT Security-09-44, Plan of Action and Milestones (POA&M) guidanceCISA BOD 26-04: How to Meet the New 3-Day Remediation SLA in GitHub